< 180msTool Call Latency
Deterministic function calling with strict JSON schema parsing and sub-200ms round-trip tool execution.
Sabrixa designs, benchmarks, and deploys enterprise-grade autonomous agent systems, deterministic RAG pipelines, and self-hosted private LLMs for venture-backed founders and scaling commercial operators.
Every AI system we deploy is measured against strict mathematical accuracy, token efficiency, and sub-200ms latency boundaries.
Deterministic function calling with strict JSON schema parsing and sub-200ms round-trip tool execution.
Contextual RAG with hybrid lexical-dense re-ranking, eliminating hallucinations from enterprise search.
Zero-retention VPC isolation, private on-premises LLM inference, and full ownership of fine-tuned weights.
Direct execution by systems and machine learning engineers. No junior trainees or non-technical account reps.
Where multi-step state machines are stress-tested, RAG vector embeddings are clustered, and private GPU inference servers are hardened.
Every AI workflow is benchmarked for sub-200ms latency, zero memory leaks, and mathematical grounding before production VPC sign-off.
We do not build toy demo wrappers. We engineer high-throughput, fault-tolerant AI systems designed to operate under strict enterprise compliance and latency requirements.
We engineer resilient state machine agents capable of multi-step tool execution, structured JSON schema validation, and human-in-the-loop exception routing without infinite loops or unbounded token costs.
“We reject brittle single-prompt chains. Every enterprise agent is engineered as a deterministic state machine with verifiable termination criteria.”
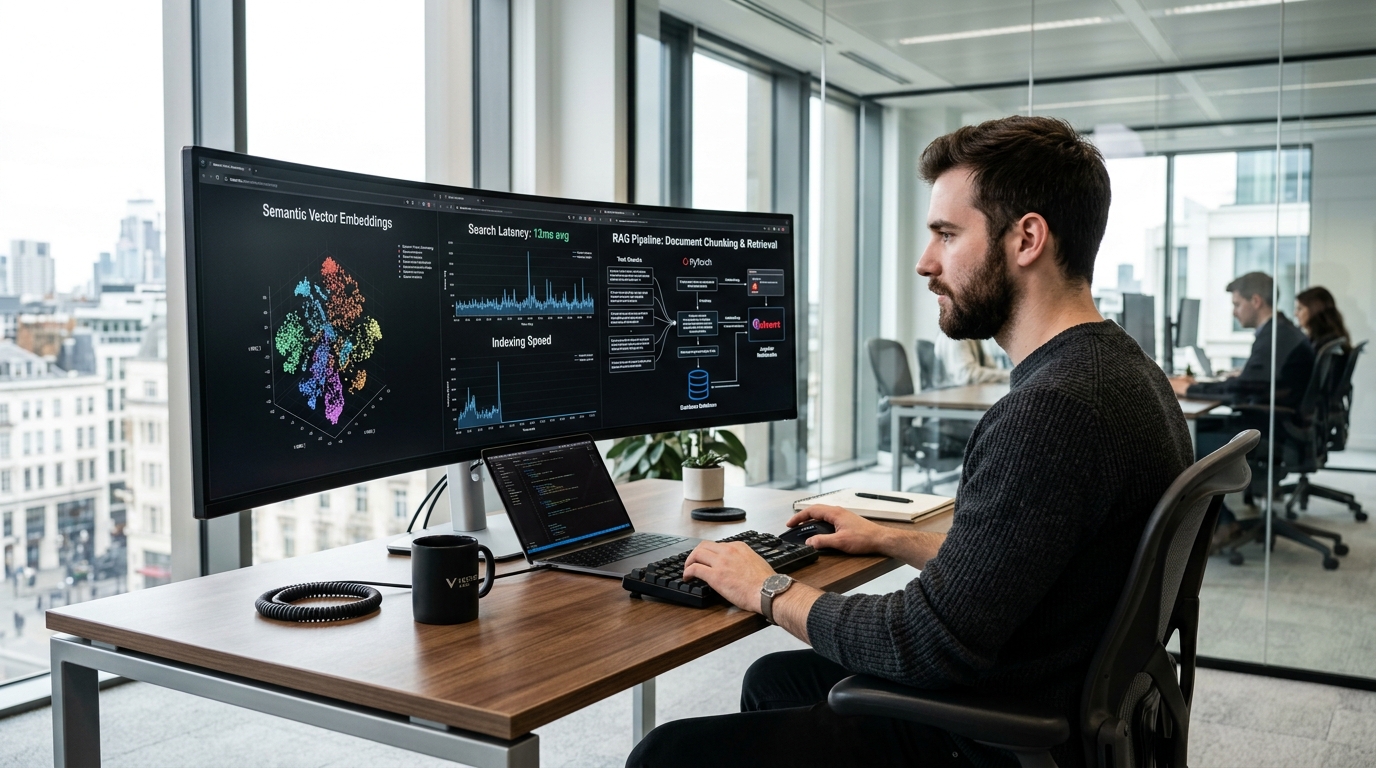
High-precision Retrieval-Augmented Generation (RAG) for complex financial filings, legal contracts, and proprietary internal knowledge. We implement contextual chunking, ColBERT late-interaction scoring, and hallucination-free answer grounding.
“Retrieval failure is the primary cause of hallucination. We guarantee citation-backed responses strictly anchored to verified enterprise source data.”
Air-gapped and VPC-isolated open-weight LLMs optimized with vLLM, TensorRT-LLM, and FP8/INT4 quantization. Complete data sovereignty compliant with DPDP Act 2023, HIPAA, and GDPR zero-data-retention mandates.
“You retain 100% intellectual property, model weights, and data sovereignty. Zero third-party API dependencies, zero vendor lock-in.”
Sub-500ms bidirectional voice systems and multimodal vision engines built on WebSockets, OpenAI Realtime API, Whisper Large v3, and Cartesia Sonic for conversational call handling and live screen intelligence.
“Conversational voice must feel instant to human ears. We optimize every millisecond between acoustic arrival, inference, and synthetic speech streaming.”
Battle-tested frameworks, state-of-the-art vector engines, and private GPU serving infrastructure with zero experimental bloat.
Rigorous model selection balancing intelligence, latency, token costs, and data privacy boundaries.
Structured workflows, tool calling, cyclic state graphs, and reliable schema parsing.
Sub-millisecond semantic search, hybrid sparse-dense indexing, and late-interaction re-ranking.
Dedicated GPU deployment engines with PagedAttention, INT4/FP8 quantization, and continuous batching.
Hallucination controls, prompt injection shields, PII redaction, and programmatic regression testing.
Deep span-level tracing, latency profiling, cost attribution, and production error triage.
Why venture founders and enterprise CTOs trust Sabrixa over generic digital agencies and no-code wrapper creators.
| Architectural Dimension | The Sabrixa Sovereign Protocol | Generic Agency AI Wrappers |
|---|---|---|
| Architectural Foundation | ✓Deterministic cyclic state machines (LangGraph) with strict schema validation and graceful fallback paths. | ✕Naive single-prompt chains or brittle no-code wrapper tools prone to catastrophic loop failures. |
| RAG & Hallucination Elimination | ✓Hybrid dense-lexical retrieval (ColBERT + Qdrant) with metadata filtering and citation grounding verification. | ✕Basic cosine distance on arbitrary document chunks with zero validation, leading to severe hallucination. |
| Data Sovereignty & Privacy | ✓Zero-retention VPC isolation or self-hosted private LLMs (vLLM / TensorRT). Full compliance with DPDP & GDPR. | ✕Direct calls to third-party public APIs with unclear data logging policies and privacy exposure. |
| Latency & Engineering SLAs | ✓Sub-180ms tool executions, streaming WebSockets, and PagedAttention optimizations with strict uptime SLAs. | ✕Unoptimized multi-second blocking calls with no streaming, yielding terrible user experience. |
| Code & Weights Ownership | ✓100% intellectual property, clean Git repository handover, model weights, and fine-tuning datasets are yours. | ✕Proprietary platform lock-in, recurring monthly markups, and zero exportable code or assets. |
| Execution Team | ✓Senior Machine Learning and Systems Engineers directly architecting and executing every sprint. | ✕Junior developers copying boilerplate tutorial scripts supervised by non-technical project managers. |
A disciplined, milestone-driven execution cycle taking you from feasibility blueprint to hardened production VPC deployment in 30 days.
We audit your data assets, define strict latency & accuracy SLAs, select optimal model topologies (frontier vs open-weight), and establish deterministic state graphs.
We deploy working vector indexing pipelines, LangGraph state machines, and structured tool calling directly on a live staging environment for early stakeholder validation.
We tune chunking strategies, optimize inference throughput via vLLM/TensorRT, benchmark under concurrent load, and configure NeMo Guardrails against adversarial prompts.
We deploy to your private AWS/GCP VPC or on-premises GPU infrastructure, execute final security penetration tests, and conduct comprehensive engineering handover.
Direct access to senior AI systems engineers with fixed-price sprint commitments and complete IP ownership.
A surgical architectural and security review of your existing AI pipelines, RAG retrieval quality, latency bottlenecks, and token cost economics.
Timeline: Delivered within 48 Business Hours
Schedule 48-Hour AuditA 2 to 4-week dedicated engineering sprint delivering production-grade AI agent systems, high-precision RAG engines, or private on-premise LLMs.
Timeline: 14–28 Business Days to Production
Book Engineering SprintContinuous fractional AI systems architecture and senior machine learning engineering partnership for scaling technology companies.
Timeline: Monthly Engineering Retainer (Quarterly Alignment)
Inquire for RetainerEvery Sabrixa model deployment complies with zero-data-retention agreements, enterprise VPC boundaries, and local regulatory laws including India DPDP Act 2023, EU GDPR, and US HIPAA. Your data is never used for model training.
Direct, technical answers to common questions asked by CTOs, technical founders, and enterprise engineering leads.
We replace naive prompt engineering with a multi-layered deterministic architecture: (1) Layout-aware document parsing with contextual chunking, (2) Hybrid lexical BM25 and dense vector retrieval with ColBERT late-interaction re-ranking, (3) Citation-grounded prompt constraints that forbid ungrounded assumptions, and (4) Programmatic post-generation validation using NeMo Guardrails and Pydantic schema verifiers before any output reaches users.
Yes. Data sovereignty is a core pillar of our practice. We specialize in deploying open-weight models (Meta Llama 3.3 70B, DeepSeek-V3/R1, Mistral Large 2) using vLLM and TensorRT-LLM inside your private cloud VPC or on-premises GPU servers. Zero data leaves your firewall, and no third-party APIs receive your sensitive customer records.
For 70B parameter models (such as Llama 3.3 70B or Qwen 2.5 72B), we recommend 2x to 4x NVIDIA A100 (80GB) or H100 GPUs using FP8/INT4 quantization with vLLM PagedAttention, easily serving 50+ concurrent requests. For smaller 8B–14B models, a single NVIDIA L4 or RTX 4090 GPU provides exceptional sub-100ms time-to-first-token performance at minimal operational cost.
We implement strict zero-data-retention agreements for frontier API endpoints (Anthropic & OpenAI enterprise tiers) and complete zero-egress networking for private VPC deployments. Automated PII detection and redaction pipelines (Microsoft Presidio) sanitize inputs before inference, and all data at rest and in transit is encrypted using AES-256 and TLS 1.3.
100% yes. From Day 1, all code is committed directly to your private GitHub/GitLab repositories. All custom fine-tuned weights (LoRA adapters), vector embeddings, database schemas, and orchestration pipelines belong exclusively to your company under standard IP assignment terms. We never implement proprietary vendor lock-in.
Every project concludes with comprehensive architectural documentation, recorded code walkthroughs, automated test suites (Promptfoo & Pytest), and hands-on pair-programming sessions with your engineers. We build software designed to be maintainable by any senior TypeScript or Python engineer without ongoing agency dependence.
Skip the experimental demo prototypes. Partner with senior ML and systems engineers to build deterministic, high-throughput AI infrastructure tailored to your enterprise.